
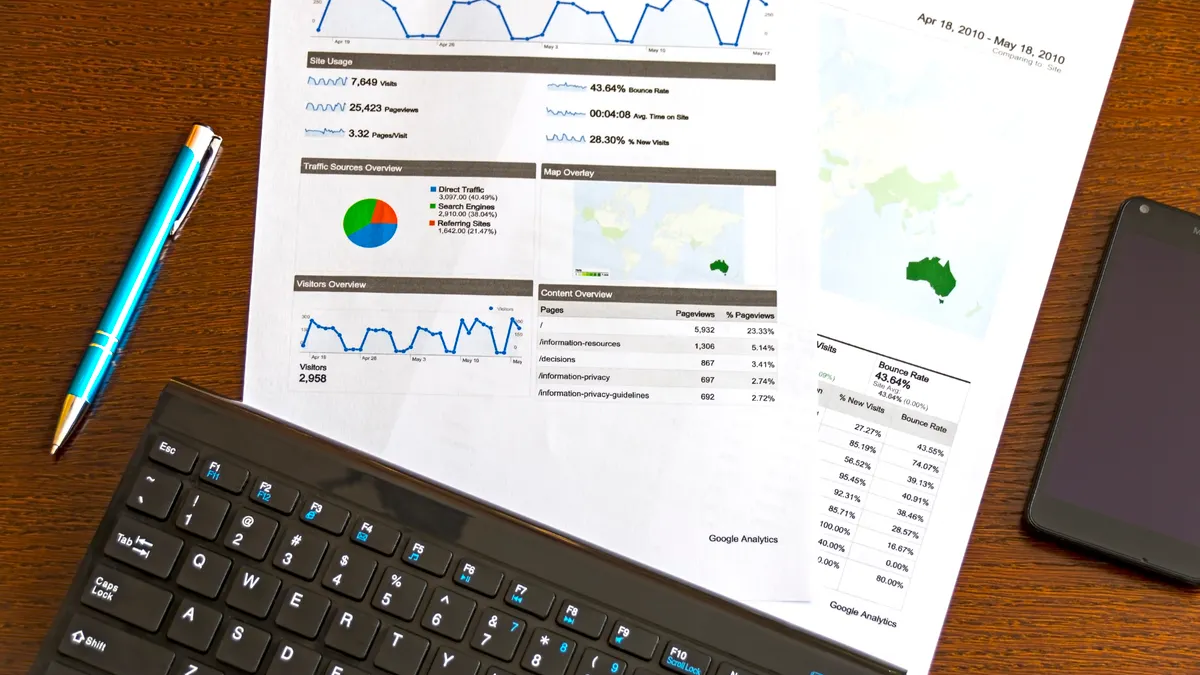
Measuring content performance when using AI writers: KPIs, A/B tests and dashboard metrics: Quick Answer: for most teams, a 90-day baseline with 1 primary…
Last updated: October 10, 2026
Key Takeaways
- Start with one page job metric, then add one quality signal and one efficiency measure.
- Use one main KPI, two supporting metrics, and one guardrail that answers “So what?”
- Test AI-generated content by changing one variable only and keeping the rest fixed.
- A useful dashboard shows trends, not decoration.
Quick Answer: for most teams, a 90-day baseline with 1 primary KPI, 2 supporting metrics, and 1 production-efficiency metric is enough to measure content performance with AI writers.
If you use AI writers, content performance should be measured on business outcomes first: qualified traffic, conversions, retention, and production efficiency. This article on measuring content performance with AI writers focuses on KPIs, A/B tests and dashboard metrics, and the trap is to judge AI content by polish alone. A clean draft that never ranks, never converts, and takes twice as long to approve is expensive content with better grammar.
I write this for content leads, SEO managers, and founders who are already producing with tools like ChatGPT, Claude, Jasper, or similar systems and now need a sane way to prove whether the workflow is helping or hurting. The answer is not “track everything.” It is to set a small scorecard, compare AI-assisted content against a human baseline, and run tests that isolate the model’s effect from topic, intent, and distribution. For broader measurement guidance, Google Search Central and Google Analytics documentation are useful starting points.
What to measure first when AI is writing your content
Start with the metric that maps to the page’s job, then add one metric for quality and one for efficiency. If a blog article is meant to rank, the main metric is not word count; it is organic sessions or impressions for the target query set. If the page is meant to capture leads, the main metric is demo requests, signups, or another conversion event in your analytics platform.
I would use three layers:
-
Outcome KPI — the business result.
- Examples: conversions, assisted conversions, revenue influenced, trial starts, demo requests.
- For editorial pages, use organic sessions, non-branded clicks, or average position as a proxy when conversion volume is too low.
-
Content quality KPI — the page’s ability to satisfy intent.
- Examples: scroll depth, engaged time, return visits, CTR from search results, internal click-throughs, or task completion.
- A page that gets traffic but a 90% bounce rate and no next step is not performing.
-
Production KPI — the cost of making the article.
- Examples: hours per published piece, edits per draft, SME review time, content cost per asset.
- AI often improves this layer first. That does not mean the content is better for the business.
The generic mistake is to let AI success mean “faster drafting.” Speed matters, but only as a denominator. A 40% faster workflow that produces 30% weaker content is a loss. Track both sides of the equation.
One more useful split: compare new content and content refreshes separately. AI often helps refreshes more than first drafts because the search intent, internal links, and source material already exist. Treating them as one pool can hide where the model is actually useful, so if the topic involves medical, legal, or financial material, consult a qualified professional and check an authoritative source before relying on the numbers.
If you need a single number to report to leadership, I would not pick an AI-generated score. I would pick a weighted score built from one business KPI, one engagement KPI, and one efficiency KPI. Keep the weights fixed for 90 days so the reporting does not become a moving target. That 90-day window also makes it easier to compare changes against a baseline in Google Analytics 4 or Search Console.
Which KPIs actually tell you AI content is working?
The best KPIs are the ones that survive a manager asking, “So what?” Usually that means one primary metric, two supporting metrics, and one guardrail. For a SaaS blog, a sensible set might be non-branded organic clicks, demo-start rate, and editor hours saved, with bounce rate or unsubscribe rate as a guardrail.
The most useful KPIs for AI-assisted content are:
- Organic clicks and impressions from Google Search Console. These show whether the page is earning search visibility.
- Conversion rate from the article. This is the clearest answer to “did the content do its job?”
- Engaged sessions or average engagement time in analytics. These help separate actual reads from accidental visits.
- Scroll depth or completion rate for long-form pieces. A 2,000-word article that only reaches 20% depth is usually misaligned with intent.
- Internal click-through rate to product pages, case studies, or next-step articles. This is a strong signal for editorial-to-revenue pathways.
- Editor and subject-matter expert time per published page. AI should lower this, or at least free time for higher-value work.
- Revisions per draft. If AI produces drafts that require five major rewrites, the workflow is not mature yet.
I would avoid vanity metrics as the headline measure. Social shares, raw pageviews, and model-generated readability scores can be useful diagnostics, but they do not tell you whether the article made money or moved the funnel.
A practical warning: some AI content inflates early engagement because it uses broad, attractive headlines. That can lift CTR while harming retention. If CTR rises and engaged time falls by 30% or more, the headline may be overselling the body. Measure both together.
There is also a difference between content-level KPIs and program-level KPIs. A single article can underperform and still be a good bet if the production process is 50% cheaper and faster. At the program level, I would watch median performance across a content cluster, not just one lucky or unlucky page. One outlier can lie; a 10-article median is harder to fool. Google’s “helpful content” guidance is a useful external benchmark here, because it pushes teams to assess usefulness rather than volume alone.
How do I A/B test AI-generated content without fooling myself?
You A/B test AI-generated content by changing one thing at a time and keeping the rest fixed: audience, placement, topic, and measurement window. If you test a new AI draft against an old article, then change the headline, the CTA, and the internal links too, you have no idea what caused the result.
Here is the core procedure I would follow:
- Choose one page type such as blog articles, landing pages, or product education pages, and keep the test within that format. A 4-week test on one page class is cleaner than a mixed bag of 30 pages.
- Define one primary KPI before launch, such as demo starts, organic clicks, or scroll completion. Secondary metrics can support the decision, but one primary KPI keeps the test honest.
- Create a control and a variant where the AI-assisted version differs in one intended way only, such as structure, headline angle, or intro length. If you want to test AI against human writing, hold the topic brief, CTA, and article template constant.
- Split traffic evenly if your testing tool allows it, or rotate publication order for matched pages. A 50/50 split is the cleanest baseline, but matched-page tests are acceptable when traffic is low.
- Run the test long enough to clear normal noise. For low-traffic pages, I would not trust a 3-day result. Give it at least 2 to 4 weeks, or longer if conversion volume is thin.
- Review both lift and cost at the end. A 6% conversion gain is less attractive if it took twice as long to edit and required heavy fact-checking.
If you are testing headlines, don’t let the AI write the body at the same time. If you are testing the body, keep the headline fixed. The same rule applies to CTAs. One variable per test is slower, but it is the only reliable way to learn anything that will hold up in a meeting.
A/B tests also need enough traffic to matter. On a page with 80 sessions a month, “winner” and “loser” are often just random variation. In low-traffic settings, I prefer a quasi-experiment: publish 5 AI-assisted pieces and 5 human-edited pieces with the same brief, then compare median outcomes over 30 to 60 days. For experimentation basics, Optimizely and the CXL testing guidance both explain why sample size and control matter.
There is a trade-off here. Strict tests are slower and less flexible, but loose tests create fake certainty. If your content budget is small, take the slower path; bad conclusions cost more than a delayed decision.
What should a content dashboard show every week?
A useful dashboard shows trend lines, not decoration. I would build a weekly view with 8 to 12 metrics max, grouped into three blocks: business impact, content health, and production efficiency. If the dashboard needs a 20-minute explanation, it is too crowded.
For business impact, include:
- Organic clicks
- Non-branded clicks
- Conversions from content
- Assisted conversions if your attribution model supports them
- Revenue or pipeline influenced, when the data is stable enough
For content health, include:
- Engagement rate or engaged sessions
- Scroll depth
- Internal click-throughs
- CTR from search results
- Pages entering or leaving the top 10 for target terms
For production efficiency, include:
- Time to first draft
- Time to publish
- Average edit rounds
- SME review time
- Cost per published asset
The most important design choice is to separate output from outcome. Publishing 24 articles in a month is output. Getting 18 of them to rank, convert, or support sales is outcome. AI tends to improve output first, so the dashboard has to prevent that from masquerading as success.
I would also tag every page by content type, funnel stage, and AI involvement level. The last tag matters more than people expect. “AI-assisted” can mean anything from idea generation to full draft generation to light editing. Those modes do not perform the same, so they should not be lumped together.
One helpful metric for AI workflows is revision density: the number of meaningful edits per 1,000 words. I am not talking about typo fixes. I mean structural changes, fact corrections, and rewrites. If revision density stays high after several cycles, the model is not saving enough time to justify itself. In practice, this is a team-level metric, so a writing lead or editor should define it consistently before reporting it.
Do not hide weak results behind aggregate averages. A dashboard that shows a 12% lift overall can still conceal the fact that product education pages improved while comparison articles fell flat. Segment by page intent or you will chase the wrong pattern. Search Console, analytics tools, and your CRM should all tell the same story before you call the article successful.
What AI content measurement gets wrong most often
The biggest mistake is confusing model quality with content quality. A smoother paragraph is not a better page if it misses the search intent or buries the CTA. Good measurement catches that gap fast, and it also helps teams see where AI is useful versus where it is not.
The common failure modes are:
- Using one metric only. A spike in traffic with flat conversions is not success.
- Comparing unlike pages. A homepage, a how-to article, and a pricing page should not share the same benchmark.
- Ignoring human edit cost. AI that creates more editorial work can still be net negative.
- Testing too many variables at once. Headline, outline, CTA, and body changes together make the result unreadable.
- Reporting averages without segments. The mean can hide that one content cluster is carrying the rest.
- Using AI scores as proof. Readability and sentiment tools are diagnostics, not a business verdict.
The honest trade-off is that tighter measurement slows publishing. A content team trying to ship 50 articles a month may not have time for pristine experiments. In that case, I would still require a baseline, even if it is rough: median traffic, median conversion rate, and median hours per article for the previous 90 days. Without a baseline, every AI win is anecdote.
This is also where AI is not the right tool. If the content’s value depends on nuanced judgment, original reporting, or sensitive subject matter, performance should be measured against accuracy and authority more than speed. AI may still help, but the KPI stack changes. For high-stakes medical, legal, or financial material, a specialist review process matters more than a fast draft. The Mayo Clinic, FDA, and FTC all publish guidance that is worth checking before you rely on automated wording.
A practical measurement setup I would trust in the first 90 days
I would start with a 90-day baseline, then compare AI-assisted content to the same period after the workflow changes. That window is long enough to smooth short-term noise without waiting a full year. Use the same analytics configuration, the same conversion definitions, and the same article template family.
The setup is simple:
- Pick 1 primary business KPI.
- Pick 2 support metrics.
- Pick 1 production-efficiency metric.
- Tag every page by AI involvement level.
- Review results every 7 days, but decide only at 30, 60, and 90 days.
- Compare medians, not just totals.
This approach is not perfect, but it is good enough to answer the question that matters: did AI writers improve the economics of your content program, or just make the calendar look fuller? If the answer is the latter, the workflow needs revision, not more volume.
FAQ
How do I know if AI content is better than human content?
Compare pages with the same intent, then judge them by the same primary KPI, usually conversion rate, organic clicks, or assisted revenue. A human article can be slower to produce and still outperform.
Should I measure word count?
No, not as a success metric. Word count can be a rough production cue, but a 700-word page that converts is better than a 2,500-word page that does nothing.
What is the best A/B test for AI writers?
The cleanest test is one article type, one audience, one variable, and one primary KPI. For example, test AI-assisted introductions against human-written introductions on the same article template for 2 to 4 weeks.
How many metrics should be on the dashboard?
Usually 8 to 12 is enough. More than that, and the dashboard becomes a report nobody reads.
Can I trust AI-generated quality scores?
Only as a rough diagnostic. They can help spot patterns, but they should not replace traffic, conversion, and editing-time data.
Drafted with AI; not yet reviewed by a person.