
Customer support workflows: using AI writing tools to generate and quality-check responses at scale: Quick Answer: For customer support workflows, using…
Last updated: October 10, 2026
Quick Answer: For customer support workflows, using AI writing tools to generate and quality-check responses at scale works best when AI drafts routine replies, a human approves sensitive cases, and the team measures quality every 30 days. In practice, that usually means a 4-stage process and a pilot of 2 or 3 ticket types.
In short: customer support workflows with AI writing tools can help draft, classify, and sanity-check support replies, but a human should stay in control of policy, tone, and anything that could affect money, access, or account status. The winning workflow is not “AI writes everything.” It is “AI handles the first pass and the rough edges, then a human approves the cases that matter.”
Key Takeaways
- AI can draft routine replies, summarize long threads, and flag gaps; it should not invent policy, promise exceptions, or close sensitive tickets.
- Build the path as four steps: classify, draft, check, and send.
- Structured support prompts produce stronger first drafts than creative-writing prompts.
- Use a short review pass that checks facts first, tone second, and completeness last.
If you run support at any kind of scale, the real problem is rarely typing speed. It is consistency. One agent writes a crisp refund reply, another sounds abrupt, a third misses a policy detail, and a fourth rewrites the same explanation for the tenth time that day. Customer support workflows with AI writing tools help most when they sit inside that mess and reduce the repetitive work without turning your queue into a hall of mirrors.
The question behind this topic is simple: how do you use customer support workflows with AI writing tools to answer more tickets without making response quality worse? My answer is to treat AI as a drafting and checking layer, not a decision-maker; for anything policy-sensitive, consult a support lead, manager, or qualified professional before sending. That means building a workflow with clear ticket types, approved response patterns, review rules, and a hard stop for edge cases, as advised in guidance from NIST’s AI Risk Management Framework and the FTC’s consumer-protection guidance on AI-related claims.
What AI should and should not do in support replies
AI should draft routine responses, summarize long threads, and flag missing details; it should not invent policy, promise exceptions, or close sensitive tickets on its own. That line matters because the fastest way to scale support badly is to let a model sound confident about things it does not know.
For simple, repeatable cases, AI is useful on the first 80% of the drafting work. Think password resets, shipping-status explanations, “how do I change X?” questions, and templated troubleshooting. The model can turn bullet points into a readable reply in seconds. It can also keep tone steady across 20 agents, which is harder than it sounds when queues are full and the same question lands 50 times a day.
The limit is just as important. AI is a poor judge of policy exceptions, account-specific promises, legal wording, abuse reports, payment disputes, and anything with a customer’s access on the line. If the reply needs judgment about a refund, a cancellation date, a chargeback, or identity verification, AI can prepare a draft, but a human should own the final wording.
I would also avoid using AI as a freeform “answer the ticket” button. That setup creates hallucinated details, duplicated policy language, and tone drift. A model is best when it is constrained by your own macros, help-center articles, and internal rules. Give it 3 to 5 approved pathways, not a blank page.
The trade-off is obvious: the tighter the guardrails, the less magical the tool feels. That is the point. Support leaders need reliability more than clever prose.
How do you build an AI-assisted support workflow?
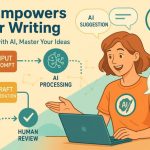
You build it by splitting the ticket path into 4 stages: classify, draft, check, and send. That structure gives AI a job at each step without letting it control the whole queue.
Here is the core procedure I would use:
- Tag the ticket type first. Route each incoming message into 1 of 5 to 10 categories, such as billing, login, shipping, product how-to, or complaint. The result is a narrower prompt and fewer wrong-turn replies.
- Pull the facts into a short summary. Use AI or a macro to condense the thread into 3 to 6 bullets: issue, customer ask, order number, policy relevant, and any deadlines. The result is less scrolling and fewer missed details.
- Generate a draft from approved material. Feed the model only the relevant help-center article, internal policy excerpt, and tone rule. Aim for a reply under 150 words for routine issues. The result is a usable first draft instead of a blank box.
- Run a quality pass against a checklist. Check for policy accuracy, names, dates, amounts, promised timelines, and whether the reply actually answers the question. The result is fewer avoidable mistakes before send.
- Escalate exceptions immediately. If the ticket includes legal threats, security concerns, account access problems, or a request outside policy, push it to a human reviewer. The result is speed without reckless automation.
That workflow works because it matches how support work already happens: triage, gather context, answer, then verify. AI is strongest when it fills the gaps between those steps.
A practical detail many teams miss is to keep the first version of this workflow small. Start with 2 queues and about 20 macros, not 200. If you try to automate every ticket type at once, you will spend more time repairing prompts than helping customers. A focused rollout also makes quality review easier, because you can compare drafts against a single standard.
The right output is not a “smart” response. It is a reply that is accurate, on-brand, and fast enough to save the customer one more follow-up.
How AI writing tools generate better first drafts
AI generates better first drafts when the input is structured like support work, not like a creative-writing prompt. A good prompt includes the issue type, the customer’s exact ask, the policy constraint, the desired tone, and the acceptable next step.
I would keep a prompt template with 5 parts:
- Ticket summary in one sentence.
- Relevant facts in bullets.
- Allowed action: refund policy, replacement policy, troubleshooting step, or escalation.
- Tone: calm, direct, apology-forward, or firm.
- Length limit: for example, 80 to 120 words for standard replies.
That structure gives the model boundaries. Without them, you get long, polished text that misses the actual question.
A useful trick is to train prompts around response patterns, not individual tickets. For example, build one draft pattern for “missing shipment,” another for “wrong item received,” and another for “password reset not working.” Each pattern should include the common facts the model needs and the one or two lines that must never change. If your shipping policy says you cannot promise delivery dates after a carrier handoff, lock that sentence into the template.
I would also keep the source material short. A 2-page policy summary is easier for a model to use than a 40-page handbook. If the model has to sift through too much text, it will either ignore important parts or over-explain. That slows the agent down and makes the final response bloated.
What this is not good for: open-ended troubleshooting, emotionally charged complaints, and tickets that require a long back-and-forth. In those cases, AI can still help summarize and suggest phrasing, but the draft should not be sent as-is.
One more practical limit: if the model cannot distinguish between “can” and “should,” it is too loose for customer-facing use. That distinction matters in support because a technically possible action may still violate policy, pricing rules, or a service-level promise.
How do you quality-check AI responses before they go out?
You quality-check AI responses with a short, repeatable review pass that checks facts first, tone second, and completeness last. If that order sounds strict, it should. A polite wrong answer is still wrong.
I would use a 6-point checklist for every AI-assisted draft:
- Does the reply answer the customer’s exact question?
- Does it match the current policy and the correct product version?
- Are names, dates, ticket numbers, and order details correct?
- Does it avoid making promises about refunds, timing, or exceptions?
- Is the tone calm and human, not stiff or over-apologetic?
- Is there a clear next step if the issue is not solved yet?
That checklist catches the most common failure modes. It also takes less than a minute once agents know it. For higher-risk queues, I would add a second review layer or require approval for certain keywords like “refund,” “account closed,” “fraud,” or “appeal.”
A good quality check is not just proofreading. It is a policy test. The most expensive mistakes in support are often tiny wording changes: “we will” instead of “we may,” or “today” instead of “within 2 business days.” AI loves smooth language, and smooth language can quietly create obligations.
I would also have the system compare the draft against a source of truth, such as an approved macro or help-center article. If the model writes something that does not appear in the approved material, that is a warning sign. It may be fine, but a human should look twice.
The trade-off here is speed. Every check adds seconds. But those seconds are cheaper than reopening tickets, issuing avoidable credits, or dealing with a customer who was misled by a polished reply.
The mistakes that make AI support workflows fail
The biggest mistake is letting AI write outside a defined policy set, which creates inconsistent promises and hidden risk. The cost is not just one bad ticket. It is the cleanup work that follows: corrections, manager escalation, and customers quoting your own wording back to you.
A second mistake is using generic prompts for every ticket. That saves setup time for about 1 week and then turns into noise. The model starts sounding confident but vague, which forces agents to rewrite almost everything. If a draft needs 5 edits every time, it is not saving time.
A third mistake is measuring only speed. Faster replies can look great in a dashboard while first-contact resolution falls. If the AI draft is too vague, customers come back with the same question, and the queue gets longer, not shorter. I would watch resolution rate, reopen rate, and escalation volume together, not just average handle time.
A fourth mistake is over-automating the most human tickets. Complaints, cancellations, fraud concerns, and account recovery often need empathy plus judgment. AI can still help with structure, but these are not the places to chase full automation.
A fifth mistake is ignoring tone consistency across channels. A reply that sounds fine in email may feel too stiff in live chat, where customers expect shorter lines and faster turn-taking. If your support stack includes both, keep separate response templates. A 3-sentence email and a 1-line chat prompt are not interchangeable.
This is where a lot of teams get disappointed. They buy AI expecting a labor shortcut, then discover they actually need process design. That is not a failure of the tool; it is the job.
What to measure so the workflow improves instead of drifting
You measure the workflow by checking both output quality and operator effort, ideally every 30 days. If you only track volume, the system will drift toward speed at the expense of trust.
I would keep the metric set small:
- first-contact resolution
- reopen rate
- escalation rate
- average editing time per draft
- QA failure rate on sampled replies
- customer satisfaction or post-case feedback, if you already collect it
Those numbers show whether AI is helping or just producing more text. If average editing time stays high, the prompts are weak. If reopen rate rises, the replies are incomplete or too generic. If QA failures cluster around one queue, that queue needs a narrower template or a stricter human review rule.
A useful standard here is sampling. Review a set of AI-assisted replies every week, not just when something goes wrong. A 10-ticket or 25-ticket sample is enough to spot recurring mistakes in wording, policy use, or missing details. You do not need a huge dataset to notice a broken pattern.
I would also track where the AI saves the most time. Often the biggest gain is not in final replies but in thread summaries and internal handoffs. That matters because support teams spend a surprising amount of time translating customer messages into usable case notes. If AI cuts that step cleanly, agents have more time for hard tickets.
The main limitation: metrics can tell you that quality is slipping, but not why. That is why review notes matter. Keep a short reason code for failures, such as “wrong policy,” “too vague,” “missed ask,” or “tone mismatch.” After 1 month, those tags usually reveal where the workflow is leaking.
FAQ
Can AI write customer support emails end to end?
Yes, for routine cases with clear policy and low risk. I would still require human review for refunds, account changes, abuse reports, and anything that could create a promise the business cannot keep.
What is the safest way to start?
Start with one queue, one template set, and one review checklist. A pilot with 2 or 3 ticket types is far easier to control than a full rollout across billing, technical support, and complaints.
Should AI responses sound conversational or formal?
They should sound like your channel and brand, but clear comes before clever. In email, that may mean a warm, concise paragraph. In chat, it often means short sentences and one question at a time.
Do I need a human to approve every AI draft?
Not every routine draft, but someone should approve high-risk categories and spot-check the rest. The more policy-sensitive the queue, the more review you need.
What is the biggest warning sign that the workflow is broken?
If agents rewrite nearly every AI draft, the system is not saving time. It is adding one more layer between the ticket and the answer.
The verdict on using AI in support workflows
AI writing tools are best used as drafting and checking engines inside a controlled support process. That setup gives you faster replies, steadier tone, and less repetitive typing without turning the model into a policy authority.
I would choose this approach for teams with a steady volume of repeat questions and clear response rules. I would not choose it for small teams with highly custom cases, or for queues where every ticket depends on judgment, exceptions, or legal sensitivity. The workflow works when the business is willing to define the guardrails first and automate second.
That is the part many generic articles skip. The tool is not the strategy. The workflow is.
Drafted with AI; not yet reviewed by a person.